Why
Why I built it
The policy acts every 0.217 s while many dodge and parry windows last only 0.1–0.2 s—and a model trained on its own fights never sees what an untried strategy would do. I wanted one live testbed to exercise RL, imitation learning, and evaluation together.
What I built
What I built
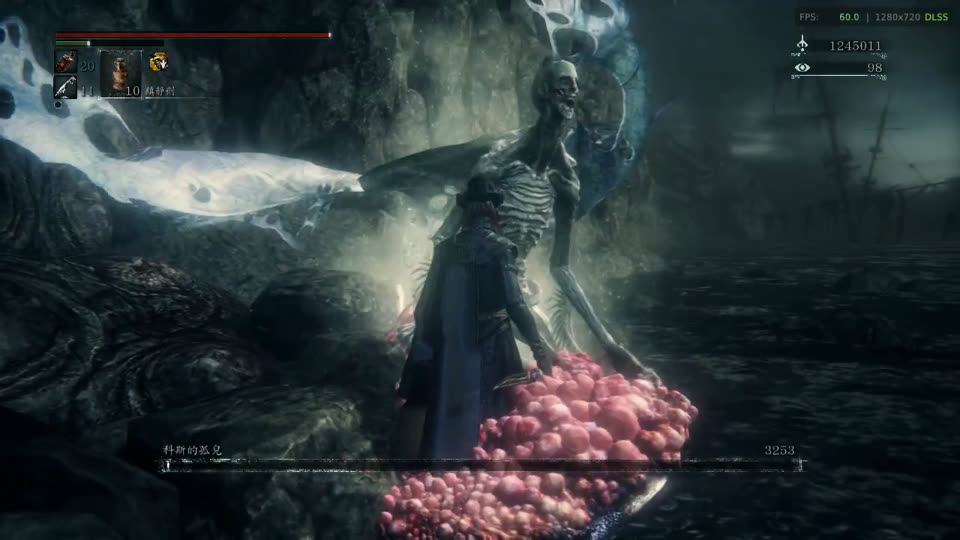
- Read-only memory observation plus a virtual gamepad: offline, zero health or damage edits, using the exact same inputs a player uses.
- A MaskablePPO policy over a 5,539-dimension state (positions, facing, terrain clearance, move timers, hit-window countdowns, resources) and 14 actions.
- A 60 Hz reflex thread predicting lightning rays and projectiles, taking over for 0.22 s only when the character’s hands are free.
- Hot-reloadable action masking that blocks only fatal inputs and leaves the rest to the network.
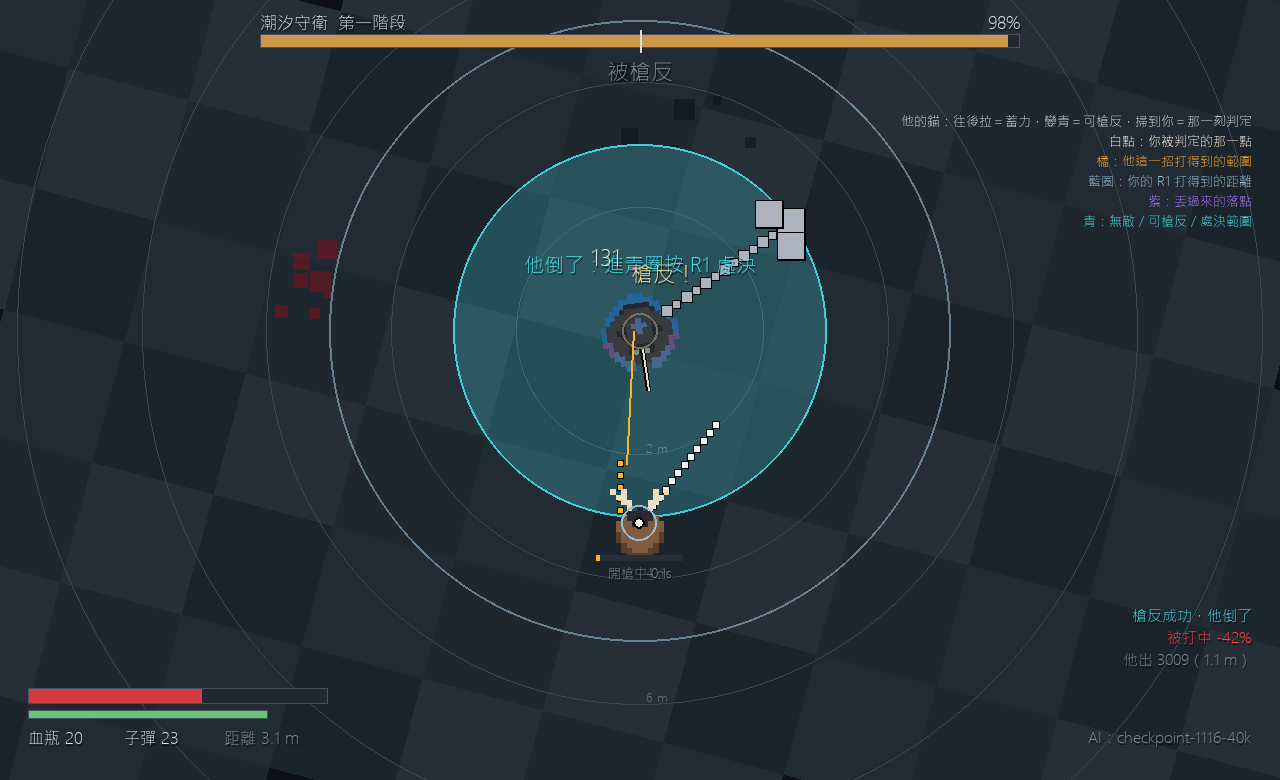
- A 60 Hz simulation dojo rebuilt from decompiled boss scripts—for playing, watching the agent, and fast training.
- Stop-on-loss review tooling that pauses on death and summarizes moves, reflexes, and distances from the final seconds.
Engineering
Problems I worked through
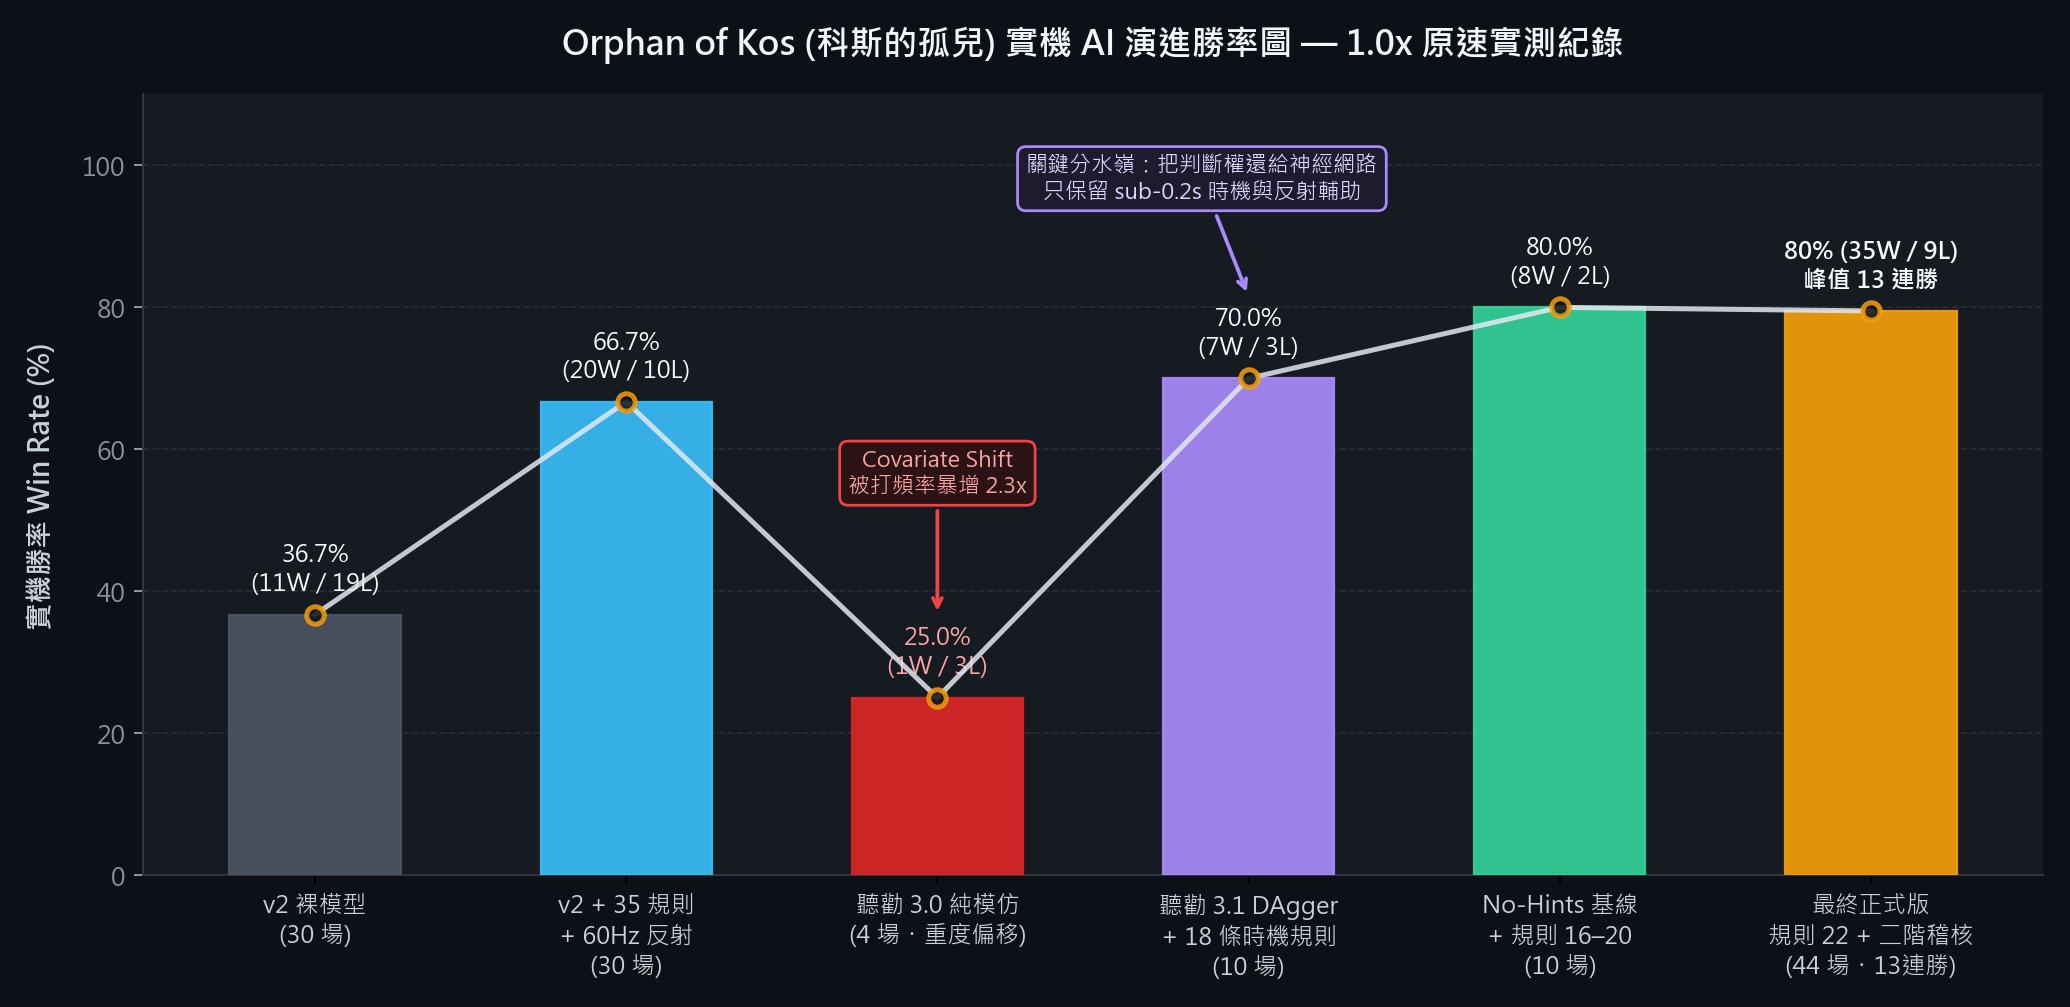
- Covariate shift: pure behavior cloning on 80 recorded fights of “policy + 35 rules” lowered offline loss, yet live hit frequency spiked 2.3× and it won 1 of 4. Switching to DAgger moved positioning and healing into the weights, leaving only sub-0.2 s timing rules and bringing wins back to 70%.
- Cross-boss transfer: Cleric Beast → Father Gascoigne → Lady Maria → Orphan of Kos, reusing 4,980 of 5,222 weights.
- Logs cannot show counterfactuals: patching deaths one by one barely moved the needle. Encoding the player habit “never let phase one close the distance,” plus a move-by-move audit of phase two, lifted win rate to 80%.
- Changes are judged across consecutive fight blocks with confidence intervals and streak odds, never on a single fight.
Role & AI
How I split the work with AI
I set the goals, input rules, and acceptance bar, watching live replays and auditing fight logs whenever it died. Claude Code, Codex, and Gemini worked on code, review, and the training dojo; I made the call on what to keep and whether the next fix meant better observations or retraining.
Trade-offs
What testing made me change
- The main policy runs at ~4.6 Hz while a 60 Hz reflex layer catches sub-0.2 s dodge and parry windows, keeping training focused on high-level spacing and decisions.
- Swapping in a more accurate hint table without retraining dropped live results to 4W / 10L: even fixing an observation shifts the policy’s input distribution.
- A misplaced wall in the dojo once taught the agent to backpedal endlessly; simulation speeds up iteration, but live runs remain the ground truth.
Outcome
Outcome
The retained hybrid build achieved 35 wins in 44 live fights at native speed with a 13-win streak and full fight logs; follow-up pure-RL, threat-radar, and dojo tracks push more decisions directly into the policy.